10.3. Timelines and Point-in-Time Recovery
Section 10.2 described the backup and recovery process in general terms. This section revisits that process, focusing on how PostgreSQL selects and switches timelines during recovery.
PostgreSQL uses a timeline to distinguish between different histories of a database cluster.
When a database cluster recovers and resumes transaction processing, its history diverges from the previous database history. PostgreSQL assigns a new timeline to identify this branched history. A timelineId identifies each timeline, and a timeline history file records the relationships among timelines.
This section describes the timeline ID and the timeline history file, explaining their roles in PITR.
10.3.1. timelineId
Each timeline is assigned a timelineId, a 4-byte unsigned integer starting at 1.
A unique timelineId belongs to each database cluster. The initdb utility creates the original database cluster with timelineId 1.
Whenever a database cluster recovers, the timelineId increases by 1. For example, in the previous section, the cluster recovered from the original one has timelineId 2.
Figure 10.4 illustrates the PITR process from the viewpoint of the timelineId.
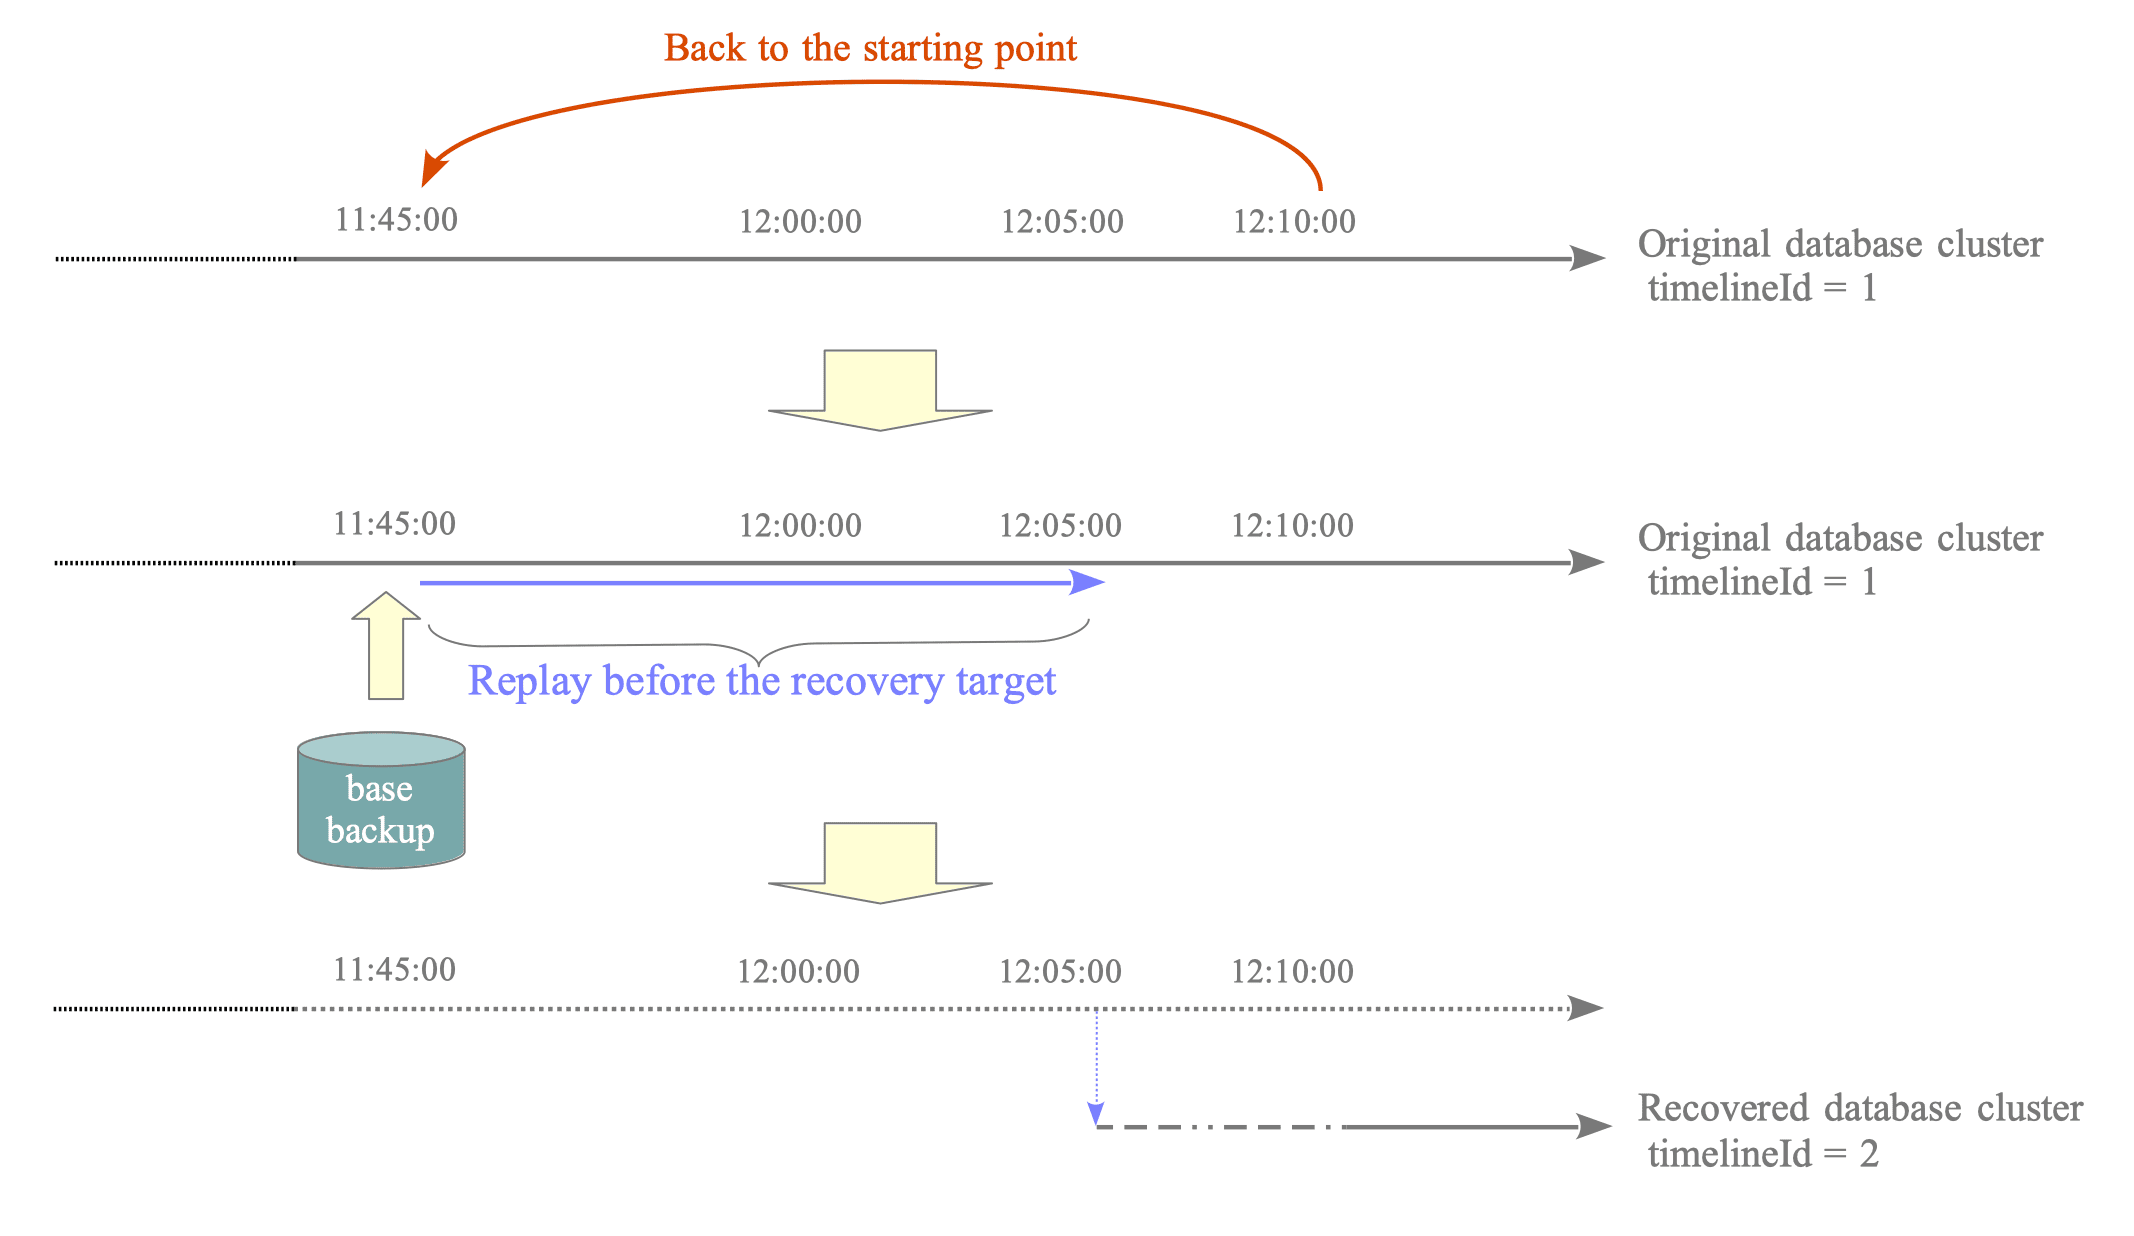
Figure 10.4. Relation of timelineId between an original and a recovered database clusters.
-
To return to the starting point of recovery, the current database cluster is removed and a base backup made in the past is restored. The red arrow curve in the figure represents this situation.
-
Next, the PostgreSQL instance starts and replays WAL data in the archive logs. This process begins from the REDO point created by pg_backup_start and continues until the recovery target by tracing the initial timeline (timelineId 1). The blue arrow line in the figure represents this situation.
-
Then, a new timelineId 2 is assigned to the recovered database cluster, and PostgreSQL runs on the new timeline.
As mentioned in Section 9.2, the first 8 digits of a WAL segment filename equal the timelineId of the database cluster that created the segment. When the timelineId changes, the WAL segment filename also changes.
The recovery process can be described again by focusing on WAL segment files. Suppose a database cluster recovers using two archive logs ‘000000010000000000000009’ and ‘00000001000000000000000A’. The newly recovered database cluster is assigned timelineId 2, and PostgreSQL creates the WAL segment starting from ‘00000002000000000000000A’.
Figure 10.5 shows this situation.
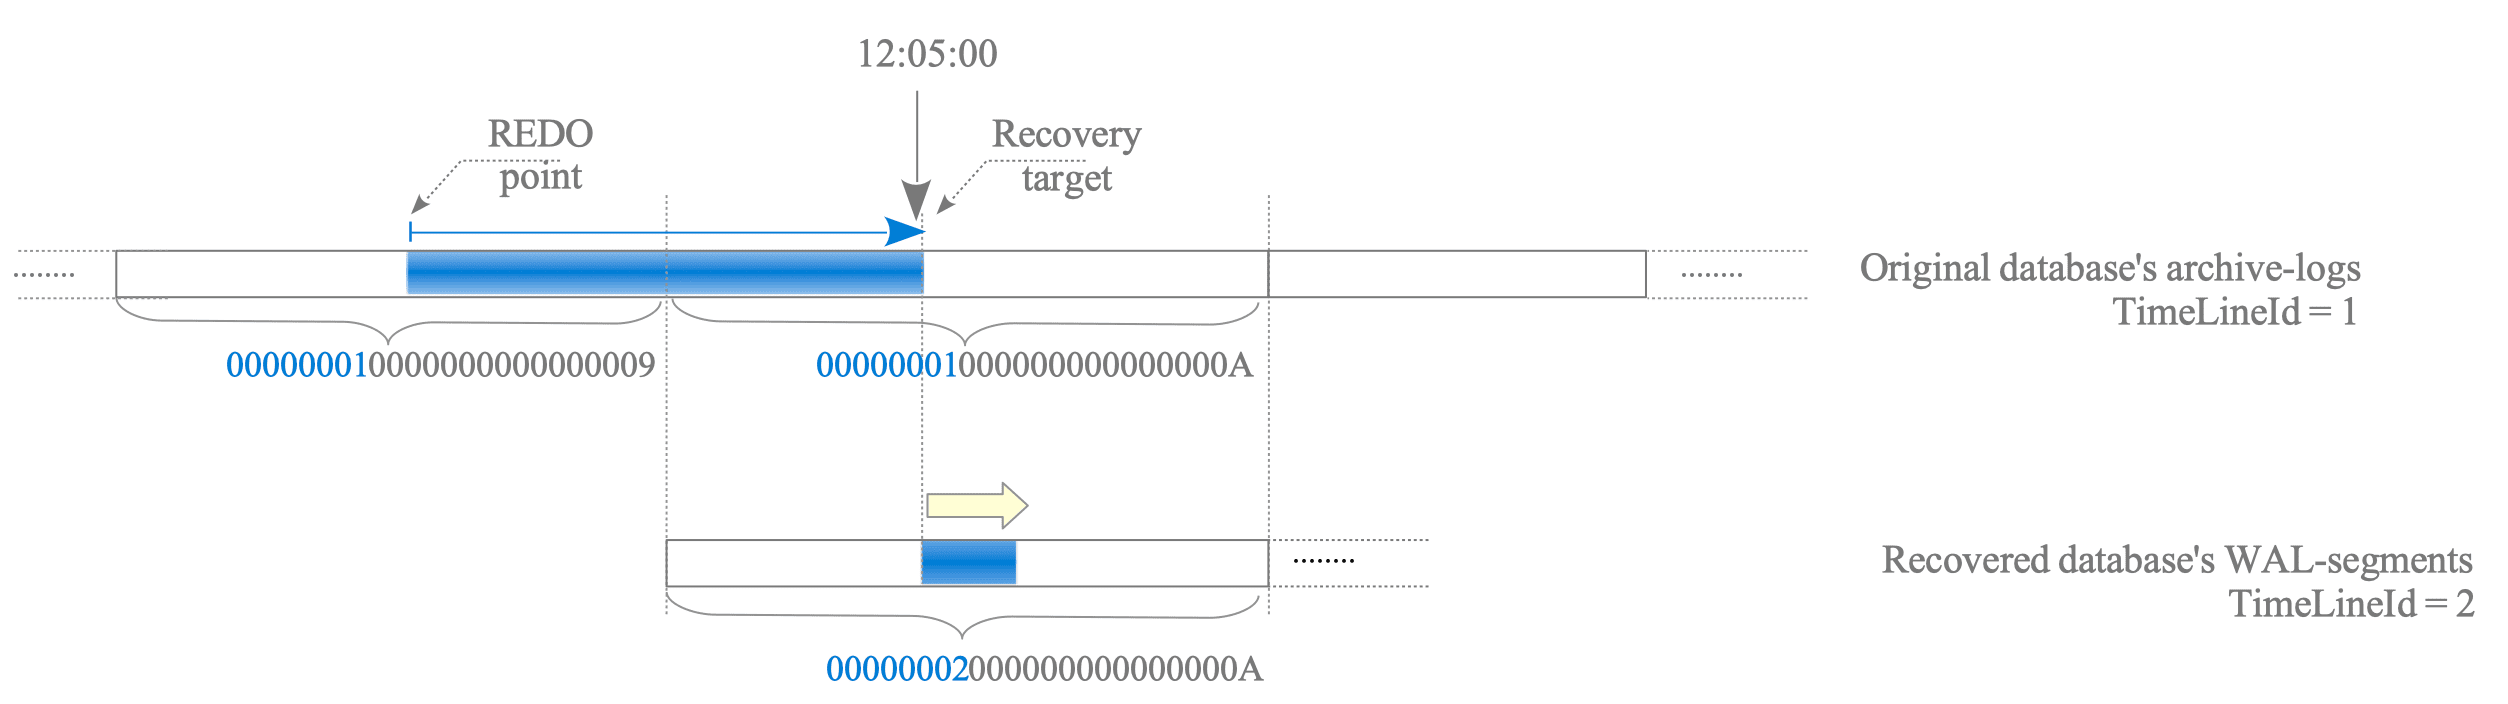
Figure 10.5. Relation of WAL segment files between an original and a recovered database clusters.
10.3.2. Timeline History File
When a PITR process completes, a timeline history file (e.g., ‘00000002.history’) is created in the archive directory and the pg_wal subdirectory (or pg_xlog in versions 9.6 or earlier). This file records which timeline it branched from and when.
The naming rule for this file is shown below:
- Timeline History File Pattern:
[TimelineId].history
The timeline history file contains at least one line, and each line is composed of the following three items:
- timelineId: The timelineId of the archive logs used for recovery.
- LSN: The LSN location where the timeline switch occurred.
- reason: A human-readable explanation of why the timeline changed.
A specific example is shown below:
$ cat /home/postgres/archivelogs/00000002.history
1	  0/A000198	before 2024-1-1 12:05:00.861324+00
The meaning is as follows:
The database cluster (timelineId 2) is based on the base backup from timelineId 1. It was recovered just before ‘2024-1-1 12:05:00.861324+00’ by replaying archive logs until LSN ‘0/A000198’.
In this way, each timeline history file provides a complete history of an individual recovered database cluster. Moreover, the PITR process itself uses this file. The next section explains the details.
The timeline history file format changed in version 9.3 (2013).
The formats are shown below:
Later version 9.3:
timelineId LSN "reason"Until version 9.2:
timelineId WAL_segment "reason"10.3.3 Point-in-Time Recovery with Timeline History File
The timeline history file is essential for performing second and subsequent Point-in-Time Recovery (PITR) operations. The following example demonstrates its utility during a second recovery attempt.
Consider a scenario where an error occurs at ‘12:15:00’ in a recovered database cluster with timeline ID 2. To recover the database to this point, the postgresql.conf file (or recovery.conf for versions 11 or earlier) should be configured as follows:
restore_command = 'cp /mnt/server/archivedir/%f %p'
recovery_target_time = "2024-1-1 12:15:00 GMT"
recovery_target_timeline = 2
The recovery_target_time parameter specifies the desired recovery time. The recovery_target_timeline parameter is set to 2 to recover along that specific timeline.
Restarting the PostgreSQL instance enters PITR mode and recovers the database to the target time along timeline ID 2 (see Figure 10.6).

Figure 10.6. Recover the database at 12:15:00 along the timelineId 2.
During recovery, PostgreSQL performs the following steps:
-
PostgreSQL reads the ‘CHECKPOINT LOCATION’ value from the backup_label file.
-
PostgreSQL reads parameter values from postgresql.conf (or recovery.conf in versions 11 or earlier); in this example, restore_command, recovery_target_time, and recovery_target_timeline.
-
PostgreSQL reads the timeline history file “00000002.history” corresponding to the recovery_target_timeline value.
-
PostgreSQL replays WAL data using these steps:
- From the REDO point to LSN ‘0/A000198’ (specified in the 00000002.history file), PostgreSQL reads and replays WAL data from archive logs with timeline ID 1.
- From the point after LSN ‘0/A000198’ to the point before timestamp ‘2024-1-1 12:15:00’, PostgreSQL reads and replays WAL data from archive logs with timeline ID 2.
-
When the recovery process completes, the current timeline ID advances to 3. PostgreSQL creates a new timeline history file “00000003.history” in the pg_wal subdirectory (pg_xlog in versions 9.6 or earlier) and the archival directory.
$ cat /home/postgres/archivelogs/00000003.history
1         0/A000198     before 2024-1-1 12:05:00.861324+00

2         0/B000078     before 2024-1-1 12:15:00.927133+00
For multiple PITR operations, the appropriate timeline ID must be explicitly set to ensure the use of the correct timeline history file.
Timeline history files serve not only as logs of the database cluster’s history but also as recovery instructions for the PITR process.